
Note
Go to the end to download the full example code.
Benchmark Gemm: numpy vs onnxruntime vs onnx-light vs onnx-light-cpu#
This example compares four ways of computing a float32 general matrix
multiplication Y = A @ B for square matrices of increasing size:
numpy -
numpy.matmul()(A @ B), which dispatches to the platform BLAS and is used here as the reference baseline.onnxruntime - running a single-node
GemmONNX model.onnx-light (built-in) - the same single-node model run through
onnx-light’sReferenceEvaluatorwithout registeringonnx-light-cpu, i.e. onnx-light’s own (non-SIMD) referenceGemmkernel. Only measured for the smaller sizes in the grid – see “Why the built-in curve stops early” below.onnx-light + onnx-light-cpu - the SIMD-accelerated
Gemmkernel thatonnx-lightdispatches to afteronnx_light_cpu.register_kernels()installs the optimized kernel implementation.
The back-ends compute the same result; the goal is to see how their timings evolve as the matrices grow.
Why the built-in curve stops early#
onnx-light’s dispatch table is a single, process-wide table:
onnx_light_cpu.register_kernels() permanently replaces the default
domain’s Gemm entry, and a given RuntimeSession resolves (and caches)
its kernels on its first run. So the only way to observe the un-accelerated,
built-in kernel and the accelerated one in the same process is to build a
separate model/session for the built-in curve and run it before
onnx_light_cpu.register_kernels() is ever called – which is what this
example does. Since the built-in kernel is a plain reference implementation
with no SIMD or blocking/packing, its cost grows much faster than the other
three back-ends; to keep the benchmark’s runtime reasonable it is only
measured on the three smallest sizes while the accelerated back-ends continue
to 4096.
Setup#
Report which SIMD level the current CPU provides. The mapping is 0=None,
1=SSE2, 2=AVX, 3=AVX2 and 4=AVX512.
import argparse
import gc
import os
import time

import numpy as np
import onnxruntime

# ``UNITTEST_GOING=1`` shrinks the benchmark (fewer/smaller sizes) so the example
# runs quickly as a unit test while still exercising every code path.
unit_test_going = os.environ.get("UNITTEST_GOING", "0") in ("1", "true", "True")

parser = argparse.ArgumentParser(description=__doc__)
parser.add_argument("-r", "--repeat", type=int, default=10 * (os.cpu_count() or 1))
parser.add_argument("-w", "--warmup", type=int, default=2 * (os.cpu_count() or 1))
parser.add_argument("-t", "--max-repeat-time", type=float, default=1.0)
args, _ = parser.parse_known_args()
if args.repeat <= 0:
    parser.error("--repeat must be greater than 0")
if args.warmup < 0:
    parser.error("--warmup must be greater than or equal to 0")
if args.max_repeat_time <= 0:
    parser.error("--max-repeat-time must be greater than 0")

# ``onnx-light`` ships ``onnx_light.onnx`` as a drop-in replacement for the
# ``onnx`` package; use it to build the model so the example depends on
# onnx-light rather than onnx.
from onnx_light.onnx import TensorProto, checker, helper
from onnx_light.onnx.reference import ReferenceEvaluator

from onnx_light_cpu import (
    clear_used_kernel_names,
    detect_simd_level,
    has_cpu_kernels,
    register_kernels,
    registered_kernel_names,
    SimdLevel,
    set_kernel_usage_recording,
    used_kernel_names,
)

_SIMD_NAMES = {
    SimdLevel.NONE: "scalar",
    SimdLevel.SSE2: "SSE2",
    SimdLevel.AVX: "AVX",
    SimdLevel.AVX2: "AVX2",
    SimdLevel.AVX512: "AVX-512",
}

assert has_cpu_kernels()
level = detect_simd_level()
simd_name = _SIMD_NAMES.get(level, level)
print(f"CPU kernels available, SIMD level: {level} ({simd_name})")
CPU kernels available, SIMD level: 4 (AVX-512)
Prime the built-in onnx-light kernel before registering onnx-light-cpu#
A dedicated model/session is run once while onnx-light-cpu’s accelerated
Gemm kernel has not been installed yet, so it resolves and caches
onnx-light’s own built-in reference kernel. It is timed below alongside the
other runtimes on the three smallest sizes.
full_size_grid = [16, 32, 64, 128, 256, 512, 1024, 2048, 4096]
size_grid = full_size_grid[:3] if unit_test_going else full_size_grid
alone_sizes = full_size_grid[:3]
rng = np.random.default_rng(0)

alone_model = make_gemm_model()
alone_session = ReferenceEvaluator(alone_model)
alone_session.run(
    None,
    {
        "A": np.zeros((1, 1), dtype=np.float32),
        "B": np.zeros((1, 1), dtype=np.float32),
    },
)
alone_times = {}

light_label = "onnx-light + onnx-light-cpu"
alone_label = "onnx-light (built-in)"
# ``register_kernels()`` needs the ``_cpuregister`` extension, which is only
# built with ``ONNX_LIGHT_CPU_WITH_ONNX_LIGHT=ON``. When it is missing (as in
# the documentation build) the onnx-light-cpu curve is simply omitted; the
# import above stays unconditional.
register_kernels()
light_session = ReferenceEvaluator(model)


def run_light(a, b):
    return light_session.run(None, {"A": a, "B": b})[0]


accelerated_kernel_name = registered_kernel_names()["Gemm"]

# onnx-light-cpu kernels record their name on every run (a mutex per call);
# only the accelerated curve would pay that cost, so disable recording to keep
# the timings fair. Recording is briefly re-enabled below to verify the exact
# implementation used for every benchmark size.
set_kernel_usage_recording(False)
Run the rest of the benchmark#
Each backend runs in its own phase. In particular, the accelerated kernel is measured before NumPy initializes a BLAS pool and before the ONNX Runtime session exists. Inputs are regenerated from the same seed in every phase.
rows_by_size = {size: [size, None, None, None] for size in size_grid}


def inputs():
    rng = np.random.default_rng(0)
    for size in size_grid:
        yield (
            size,
            rng.standard_normal((size, size)).astype(np.float32),
            rng.standard_normal((size, size)).astype(np.float32),
        )


for size, a, b in inputs():
    set_kernel_usage_recording(True)
    clear_used_kernel_names()
    run_light(a, b)
    accelerated_kernel_names = used_kernel_names()
    assert accelerated_kernel_name in accelerated_kernel_names, accelerated_kernel_names
    set_kernel_usage_recording(False)
    rows_by_size[size][2] = measure(
        lambda a=a, b=b: run_light(a, b),
        args.repeat,
        args.warmup,
        args.max_repeat_time,
    )

for size, a, b in inputs():
    if size not in alone_sizes:
        continue
    alone_times[size] = measure(
        lambda a=a, b=b: alone_session.run(None, {"A": a, "B": b}),
        args.repeat,
        args.warmup,
        args.max_repeat_time,
    )

for size, a, b in inputs():
    expected = a @ b
    np.testing.assert_allclose(run_light(a, b), expected, rtol=1e-2, atol=1e-2)
    if size in alone_sizes:
        np.testing.assert_allclose(
            alone_session.run(None, {"A": a, "B": b})[0],
            expected,
            rtol=1e-2,
            atol=1e-2,
        )

plot_light_results = light_session is not None
light_session = None
alone_session = None
gc.collect()

for size, a, b in inputs():
    rows_by_size[size][1] = measure(
        lambda a=a, b=b: a @ b, args.repeat, args.warmup, args.max_repeat_time
    )

session = onnxruntime.InferenceSession(model_bytes, providers=["CPUExecutionProvider"])
for size, a, b in inputs():
    rows_by_size[size][3] = measure(
        lambda a=a, b=b: session.run(None, {"A": a, "B": b}),
        args.repeat,
        args.warmup,
        args.max_repeat_time,
    )

for _size, a, b in inputs():
    expected = a @ b
    np.testing.assert_allclose(
        session.run(None, {"A": a, "B": b})[0], expected, rtol=1e-2, atol=1e-2
    )

rows = [tuple(rows_by_size[size]) for size in size_grid]
for size, numpy_time, cpu_time, ort_time in rows:
    alone_text = f"{alone_times[size] * 1e6:10.2f} us" if size in alone_times else "not measured"
    print(
        f"size={size:>4}x{size:<4} | numpy={numpy_time * 1e6:10.2f} us | "
        f"onnx-light={alone_text} | "
        f"onnx-light-cpu={cpu_time * 1e6:10.2f} us | "
        f"onnxruntime={ort_time * 1e6:10.2f} us"
    )

print(
    "verified onnx-light-cpu Gemm for every benchmark size: "
    f"accelerated={accelerated_kernel_name}"
)
set_kernel_usage_recording(True)

sizes = np.array([r[0] for r in rows])
numpy_times = np.array([r[1] for r in rows])
cpu_times = np.array([r[2] for r in rows])
ort_times = np.array([r[3] for r in rows])
alone_grid = np.array(alone_sizes)
alone_grid_times = np.array([alone_times[size] for size in alone_sizes])
size=  16x16   | numpy=      1.14 us | onnx-light=      3.09 us | onnx-light-cpu=      2.44 us | onnxruntime=      7.46 us
size=  32x32   | numpy=      1.89 us | onnx-light=      3.25 us | onnx-light-cpu=      3.05 us | onnxruntime=      8.07 us
size=  64x64   | numpy=      5.80 us | onnx-light=      9.20 us | onnx-light-cpu=      8.99 us | onnxruntime=     14.21 us
size= 128x128  | numpy=     30.27 us | onnx-light=not measured | onnx-light-cpu=     25.44 us | onnxruntime=     52.44 us
size= 256x256  | numpy=    187.62 us | onnx-light=not measured | onnx-light-cpu=    214.88 us | onnxruntime=    345.02 us
size= 512x512  | numpy=   1285.39 us | onnx-light=not measured | onnx-light-cpu=   1674.97 us | onnxruntime=   1307.68 us
size=1024x1024 | numpy=  10083.61 us | onnx-light=not measured | onnx-light-cpu=  11371.42 us | onnxruntime=  15810.30 us
size=2048x2048 | numpy=  79090.71 us | onnx-light=not measured | onnx-light-cpu=  94351.43 us | onnxruntime= 128503.52 us
size=4096x4096 | numpy= 621650.11 us | onnx-light=not measured | onnx-light-cpu= 746767.21 us | onnxruntime=1013797.54 us
verified onnx-light-cpu Gemm for every benchmark size: accelerated=onnx_light_cpu::Gemm
Plot the timings#
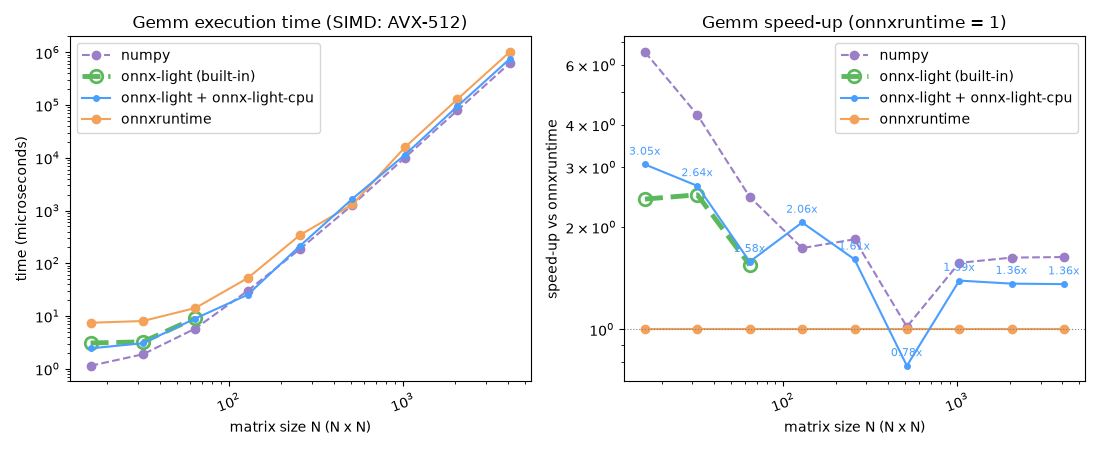
The left panel shows the raw execution time versus the matrix size on a
log-log scale. The right panel shows the speed-up relative to
onnxruntime (the baseline): for each back-end the onnxruntime time is
divided by the back-end time, so values above 1 are faster than
onnxruntime and values below 1 are slower. The speed-up is drawn on a
logarithmic y-axis so that a given ratio and its reciprocal are equidistant
from the 1 baseline. The built-in onnx-light curve
only has points for the sizes it was measured on (see “Why the built-in
curve stops early” above).
import matplotlib.pyplot as plt

fig, (ax_time, ax_speedup) = plt.subplots(1, 2, figsize=(11, 4.5))

ax_time.plot(sizes, numpy_times * 1e6, "o--", label="numpy", color="#9b7ec8")
ax_time.plot(
    alone_grid,
    alone_grid_times * 1e6,
    "o--",
    label=alone_label,
    color="#5cb85c",
    linewidth=3.5,
    markersize=9,
    markerfacecolor="none",
    markeredgewidth=2,
    zorder=2,
)
if plot_light_results:
    ax_time.plot(
        sizes,
        cpu_times * 1e6,
        "o-",
        label=light_label,
        color="#4a9eff",
        linewidth=1.5,
        markersize=4,
        zorder=3,
    )
ax_time.plot(sizes, ort_times * 1e6, "o-", label="onnxruntime", color="#f4a259")
ax_time.set_xscale("log")
ax_time.set_yscale("log")
ax_time.set_xlabel("matrix size N (N x N)")
ax_time.set_ylabel("time (microseconds)")
ax_time.set_title(f"Gemm execution time (SIMD: {simd_name})")
ax_time.tick_params(axis="x", labelrotation=20)
ax_time.legend()

ort_times_by_size = dict(zip(sizes.tolist(), ort_times.tolist(), strict=True))
alone_ort_times = np.array([ort_times_by_size[size] for size in alone_sizes])

ax_speedup.plot(sizes, ort_times / numpy_times, "o--", label="numpy", color="#9b7ec8")
ax_speedup.plot(
    alone_grid,
    alone_ort_times / alone_grid_times,
    "o--",
    label=alone_label,
    color="#5cb85c",
    linewidth=3.5,
    markersize=9,
    markerfacecolor="none",
    markeredgewidth=2,
    zorder=2,
)
if plot_light_results:
    cpu_speedup = ort_times / cpu_times
    ax_speedup.plot(
        sizes,
        cpu_speedup,
        "o-",
        label=light_label,
        color="#4a9eff",
        linewidth=1.5,
        markersize=4,
        zorder=3,
    )
    for size, speedup in zip(sizes, cpu_speedup, strict=True):
        ax_speedup.annotate(
            f"{speedup:.2f}x",
            (size, speedup),
            xytext=(0, 7),
            textcoords="offset points",
            ha="center",
            fontsize=8,
            color="#4a9eff",
        )
ax_speedup.plot(sizes, ort_times / ort_times, "o-", label="onnxruntime", color="#f4a259")
ax_speedup.axhline(1.0, color="grey", linewidth=0.8, linestyle=":")
ax_speedup.set_xscale("log")
ax_speedup.set_yscale("log")
ax_speedup.set_xlabel("matrix size N (N x N)")
ax_speedup.set_ylabel("speed-up vs onnxruntime")
ax_speedup.set_title("Gemm speed-up (onnxruntime = 1)")
ax_speedup.tick_params(axis="x", labelrotation=20)
ax_speedup.legend()

fig.tight_layout()
fig.savefig("plot_gemm_benchmark.png")
plt.show()
Total running time of the script: (0 minutes 23.100 seconds)