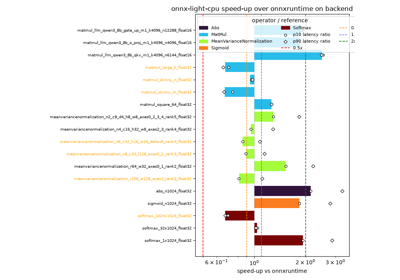
Benchmarks#
A gallery of benchmarks comparing the SIMD-accelerated CPU kernels provided by
onnx-light-cpu against other back-ends such as numpy, onnxruntime
and onnx-light’s built-in reference kernels.
The Gemm and Attention corpora used by the
Gemm and MatMul roadmap are implemented
as C++ backend cases in TestMode::BENCHMARK. This is the benchmark framework
provided by onnx-light: cases are generated lazily in C++, exposed through
CollectTestCases, and consumed by the common benchmark recorder. The Gemm
cases live in
onnx_light_cpu/backend_test/cases/math/cases_gemm.cc; the Attention cases
live in onnx-light’s C++ backend-test registry.
The Gemm corpus contains shape-forced cases for every prepared algorithm:
direct (small K), skinny_m, skinny_n, split_k (large K with a
small output), and square/transformer shapes (general five-loop). Every shape
is registered for each element type the GemmKernel implements – float32,
float16 and bfloat16 – so the corpus also measures the fp16/bf16
widen/round-trip overhead. Standalone recorders run on their calling thread.
Integration benchmarks compare participant counts through the onnx-light
session cpu_execution policy, which owns thread count, affinity, and spin
behavior. onnx-light-cpu does not create workers or read thread-control
environment variables.
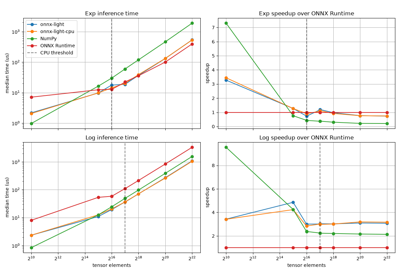
The unary backend corpus samples both sides of the Exp and Log
scheduling thresholds. plot_exp_log_benchmark.py visualizes those
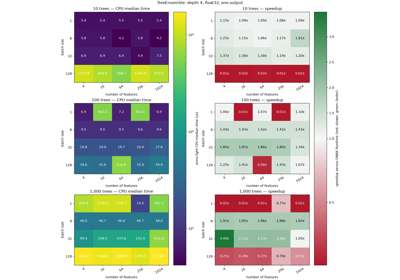
transitions. plot_tree_ensemble_benchmark.py visualizes representative
cases from the maintained TreeEnsemble parity runner; it does not claim
backend-test kernel coverage because TreeEnsemble is not registered there.
plot_backend_cases_benchmark.py walks a subset of the TestMode::BENCHMARK
test_cpu_* backend test cases – covering every operator with an
onnx-light-cpu backend test registration (Abs, Exp, Log, Gemm
and Not) – and times each one through onnx-light (with onnx-light-cpu’s
accelerated kernels registered) and through ONNX Runtime, using the exact same
generated model and inputs for both.
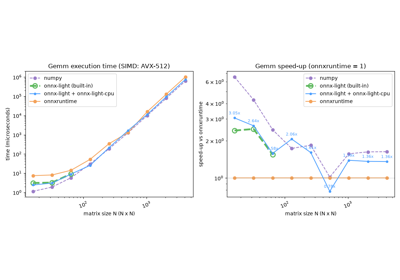
Benchmark Gemm: numpy vs onnxruntime vs onnx-light vs onnx-light-cpu

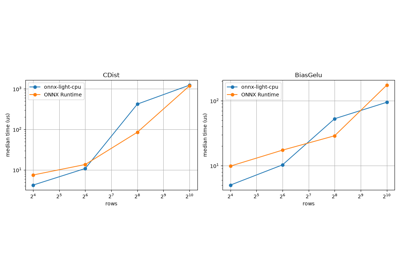
Benchmark Abs: onnxruntime vs onnx-light + onnx-light-cpu
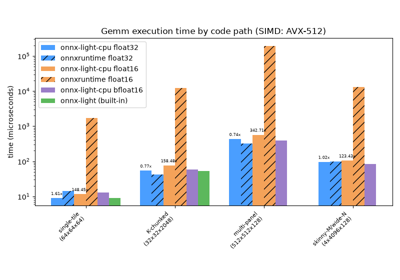
Benchmark Gemm: float32 vs float16 vs bfloat16 across kernel code paths