Note
Go to the end to download the full example code.
Custom ops: ORT called by onnx-light#
The standalone onnx-light host loads an independent ORT LeakyRelu custom-op library,
compiled using only the public ORT headers and its own numerical code.
It then runs the optimized onnx_light_cpu::Log through the same ORT custom-op ABI.
This script does not import or load ONNX Runtime.
import os
from pathlib import Path

import numpy
import matplotlib.pyplot as plt
from onnx_light.onnx import TensorProto, checker, helper

from onnx_light_ort import CustomOpSession
This first host profile accepts one float32 CPU custom node. Unsupported signatures, opsets and API versions fail explicitly.
model = helper.make_model(
    helper.make_graph(
        [helper.make_node("LeakyRelu", ["X"], ["Y"], domain="ort_custom_ops", alpha=0.125)],
        "ort-custom-op-in-onnx-light",
        [helper.make_tensor_value_info("X", TensorProto.FLOAT, ["N"])],
        [helper.make_tensor_value_info("Y", TensorProto.FLOAT, ["N"])],
    ),
    opset_imports=[helper.make_opsetid("ort_custom_ops", 1)],
    ir_version=9,
)
checker.check_model(model)
The library path is caller-owned: native plugins execute trusted code and are never discovered from the model. Kernels are retained between runs.
host = Path(os.environ["ONNX_LIGHT_ORT_HOST_LIBRARY"]).resolve(strict=True)
library = Path(os.environ["ONNX_LIGHT_ORT_INCOMING_CUSTOM_OP_LIBRARY"]).resolve(strict=True)
values = numpy.array([-4, -1, 0, 2], dtype=numpy.float32)
with CustomOpSession(model, library=library, host_library=host) as session:
    result = session.run(["Y"], {"X": values})[0]
    numpy.testing.assert_array_equal(result, [-0.5, -0.125, 0, 2])
    other = numpy.array([1, -2], dtype=numpy.float32)
    numpy.testing.assert_array_equal(
        session.run(None, {"X": other})[0], numpy.where(other < 0, other * 0.125, other)
    )
print("ORT custom op called by onnx-light:", result)
ORT custom op called by onnx-light: [-0.5 -0.125 0. 2. ]
The incoming bridge can also execute our CPU plugin: its API-18 descriptor uses exactly the audited one-float32-input/output profile. Loading that custom-op library does not load ONNX Runtime or connect the two common libraries.
cpu_model = helper.make_model(
    helper.make_graph(
        [helper.make_node("Log", ["X"], ["Y"], domain="onnx_light_cpu")],
        "cpu-log-custom-op-called-by-onnx-light",
        [helper.make_tensor_value_info("X", TensorProto.FLOAT, ["N"])],
        [helper.make_tensor_value_info("Y", TensorProto.FLOAT, ["N"])],
    ),
    opset_imports=[helper.make_opsetid("onnx_light_cpu", 1)],
    ir_version=9,
)
checker.check_model(cpu_model)
cpu_library = Path(os.environ["ONNX_LIGHT_ORT_PLUGIN_LIBRARY"]).resolve(strict=True)
cpu_values = numpy.linspace(0.01, 10, 33, dtype=numpy.float32)
with CustomOpSession(cpu_model, library=cpu_library, host_library=host) as session:
    cpu_result = session.run(None, {"X": cpu_values})[0]
    numpy.testing.assert_allclose(cpu_result, numpy.log(cpu_values), rtol=2e-6, atol=0)
print("CPU Log through the ORT custom-op ABI, called by onnx-light:", cpu_result)
CPU Log through the ORT custom-op ABI, called by onnx-light: [-4.6051702  -1.1326215  -0.45511505 -0.05491825  0.23011914  0.45167258
  0.6329326   0.7863244   0.91928625  1.0366261   1.1416318   1.2366517
  1.3234211   1.403259    1.4771913   1.5460321   1.6104374   1.6709445
  1.7279985   1.7819722   1.8331813   1.8818953   1.9283462   1.9727346
  2.0152364   2.056005    2.0951765   2.1328712   2.1691966   2.2042484
  2.2381132   2.2708688   2.3025851 ]
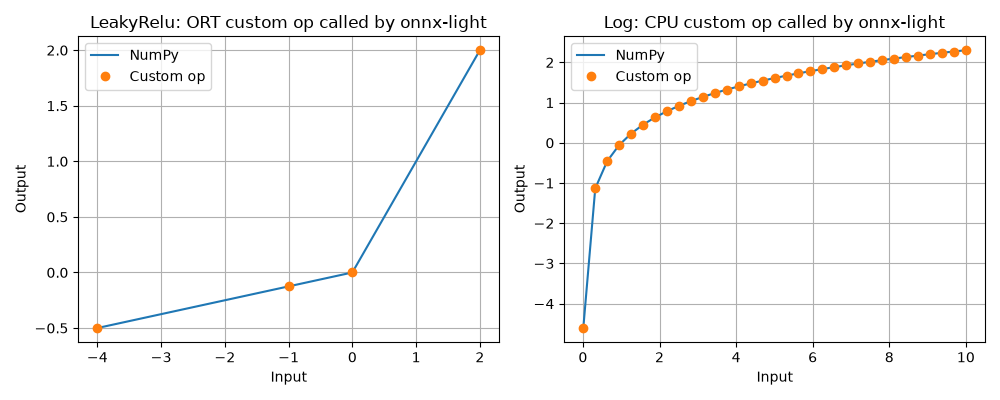
Plot the standalone host’s outputs alongside the NumPy references.
fig, axes = plt.subplots(1, 2, figsize=(10, 4))
axes[0].plot(values, numpy.where(values < 0, values * 0.125, values), label="NumPy")
axes[0].plot(values, result, "o", label="Custom op")
axes[0].set(
    title="LeakyRelu: ORT custom op called by onnx-light", xlabel="Input", ylabel="Output"
)
axes[1].plot(cpu_values, numpy.log(cpu_values), label="NumPy")
axes[1].plot(cpu_values, cpu_result, "o", label="Custom op")
axes[1].set(title="Log: CPU custom op called by onnx-light", xlabel="Input", ylabel="Output")
for ax in axes:
    ax.legend()
    ax.grid(True)
fig.tight_layout()
plt.show()
Total running time of the script: (0 minutes 0.178 seconds)