Note
Go to the end to download the full example code.
Custom ops: onnx-light called by ORT#
The real ORT host loads native LeakyRelu and optimized CPU Log custom ops.
The model calls the custom domain explicitly; no EP is involved.
import os
from pathlib import Path

import numpy
import onnxruntime
import matplotlib.pyplot as plt
from onnx_light.onnx import TensorProto, checker, helper
Create a model calling the custom domain onnx_light.
model = helper.make_model(
    helper.make_graph(
        [helper.make_node("LeakyRelu", ["X"], ["Y"], domain="onnx_light", alpha=0.125)],
        "onnx-light-in-ort",
        [helper.make_tensor_value_info("X", TensorProto.FLOAT, [4])],
        [helper.make_tensor_value_info("Y", TensorProto.FLOAT, [4])],
    ),
    opset_imports=[
        helper.make_opsetid("", 18),
        helper.make_opsetid("onnx_light", 1),
    ],
    ir_version=9,
)
checker.check_model(model)
ORT supplies its API table and allocates the outputs. The plugin delegates the numerical work to onnx-light’s native CPU kernel.
library = Path(os.environ["ONNX_LIGHT_ORT_PLUGIN_LIBRARY"]).resolve(strict=True)
options = onnxruntime.SessionOptions()
options.intra_op_num_threads = 1
options.inter_op_num_threads = 1
options.register_custom_ops_library(str(library))
session = onnxruntime.InferenceSession(
    model.SerializeToString(), options, providers=["CPUExecutionProvider"]
)
values = numpy.array([-4, -1, 0, 2], dtype=numpy.float32)
result = session.run(["Y"], {"X": values})[0]
numpy.testing.assert_array_equal(result, [-0.5, -0.125, 0, 2])
print("onnx-light custom op called by ORT:", result)
onnx-light custom op called by ORT: [-0.5 -0.125 0. 2. ]
The same library also exposes onnx_light_cpu::Log. Its numerical code
comes from onnx-light-cpu’s standalone ml_cpu_compute library, with
runtime SIMD dispatch and no additional onnx-light runtime or worker pool.
cpu_model = helper.make_model(
    helper.make_graph(
        [helper.make_node("Log", ["X"], ["Y"], domain="onnx_light_cpu")],
        "cpu-log-custom-op-called-by-ort",
        [helper.make_tensor_value_info("X", TensorProto.FLOAT, [3, 7])],
        [helper.make_tensor_value_info("Y", TensorProto.FLOAT, [3, 7])],
    ),
    opset_imports=[helper.make_opsetid("onnx_light_cpu", 1)],
    ir_version=9,
)
checker.check_model(cpu_model)
cpu_session = onnxruntime.InferenceSession(
    cpu_model.SerializeToString(), options, providers=["CPUExecutionProvider"]
)
cpu_values = numpy.linspace(0.01, 10, 21, dtype=numpy.float32).reshape(3, 7)
cpu_result = cpu_session.run(None, {"X": cpu_values})[0]
numpy.testing.assert_allclose(cpu_result, numpy.log(cpu_values), rtol=2e-6, atol=0)
print("onnx-light-cpu Log custom op called by ORT:\n", cpu_result)
onnx-light-cpu Log custom op called by ORT:
 [[-4.6051702  -0.67432535  0.00895969  0.41111577  0.69713914  0.91928625
   1.1009429 ]
 [ 1.2546184   1.3877933   1.5052989   1.6104374   1.7055659   1.7924259
   1.8723404 ]
 [ 1.9463387   2.0152364   2.0796914   2.1402426   2.1973357   2.2513444
   2.3025851 ]]
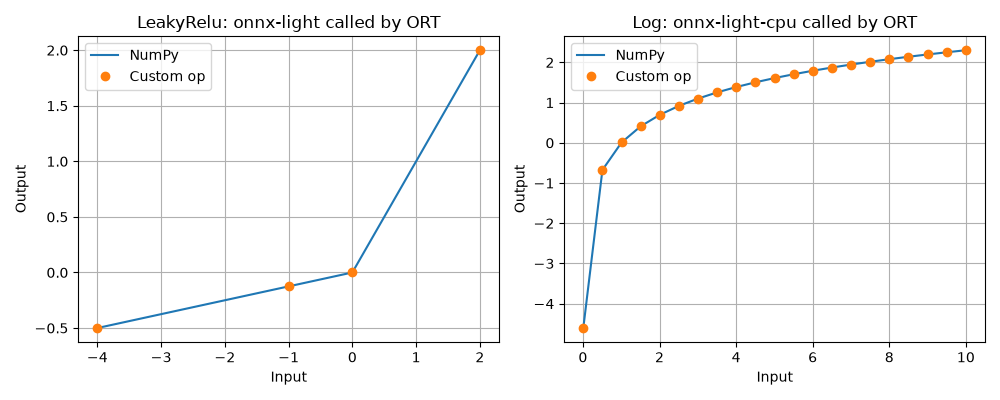
Compare the custom-op outputs with their NumPy references.
fig, axes = plt.subplots(1, 2, figsize=(10, 4))
axes[0].plot(values, numpy.where(values < 0, values * 0.125, values), label="NumPy")
axes[0].plot(values, result, "o", label="Custom op")
axes[0].set(title="LeakyRelu: onnx-light called by ORT", xlabel="Input", ylabel="Output")
axes[1].plot(cpu_values.ravel(), numpy.log(cpu_values).ravel(), label="NumPy")
axes[1].plot(cpu_values.ravel(), cpu_result.ravel(), "o", label="Custom op")
axes[1].set(title="Log: onnx-light-cpu called by ORT", xlabel="Input", ylabel="Output")
for ax in axes:
    ax.legend()
    ax.grid(True)
fig.tight_layout()
plt.show()
Total running time of the script: (0 minutes 0.269 seconds)